Designing latency budgets for real-time AI
A practical way to break an AI response into network, queue, preprocessing, inference, and application budgets before choosing where it should run.
Read articleNYR blog
Architecture, infrastructure, and hard-won lessons for teams building AI that has to perform beyond a distant cloud.
 Featured
A practical way to break an AI response into network, queue, preprocessing, inference, and application budgets before choosing where it should run.
Read articleFrom the NYR team
5 articles
 01Edge AI fundamentals
Learn how edge AI runs inference closer to users, devices, and data, and when local deployment is the right architecture for an AI product.
 02Reliability
How to define local autonomy, degraded modes, recovery, and data synchronization for AI products deployed at customer sites.
 03Architecture
Compare edge AI and cloud AI across latency, privacy, availability, cost, operations, and personalization to choose the right deployment model.
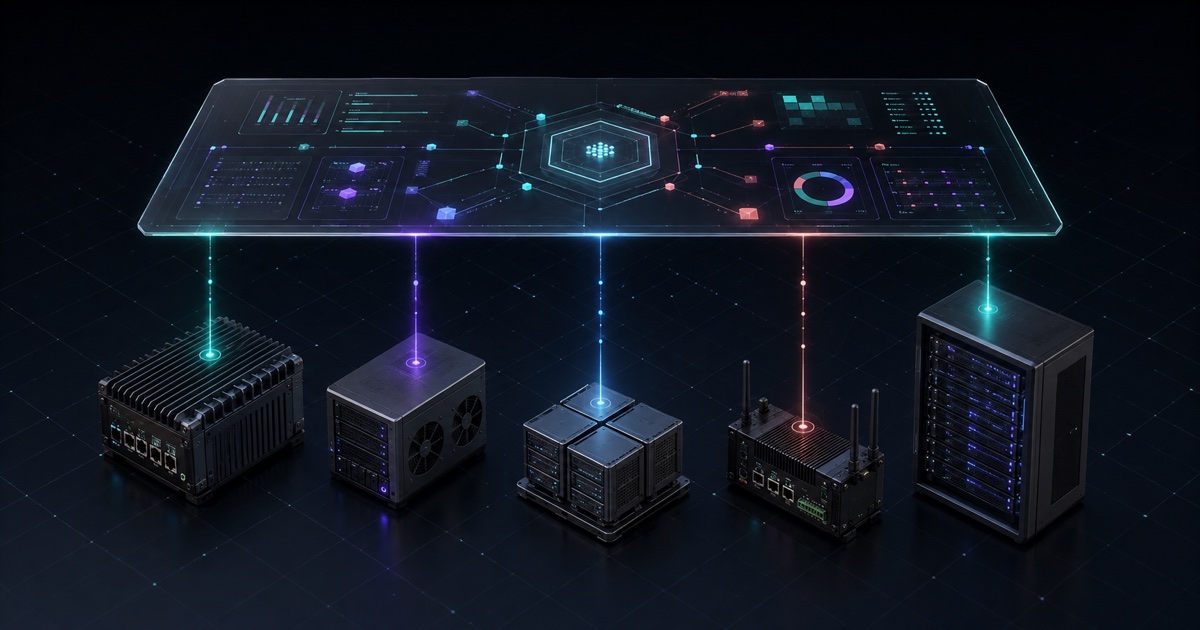 04Infrastructure
The abstractions an AI platform needs to place, update, observe, and recover workloads across unlike customer-site infrastructure.
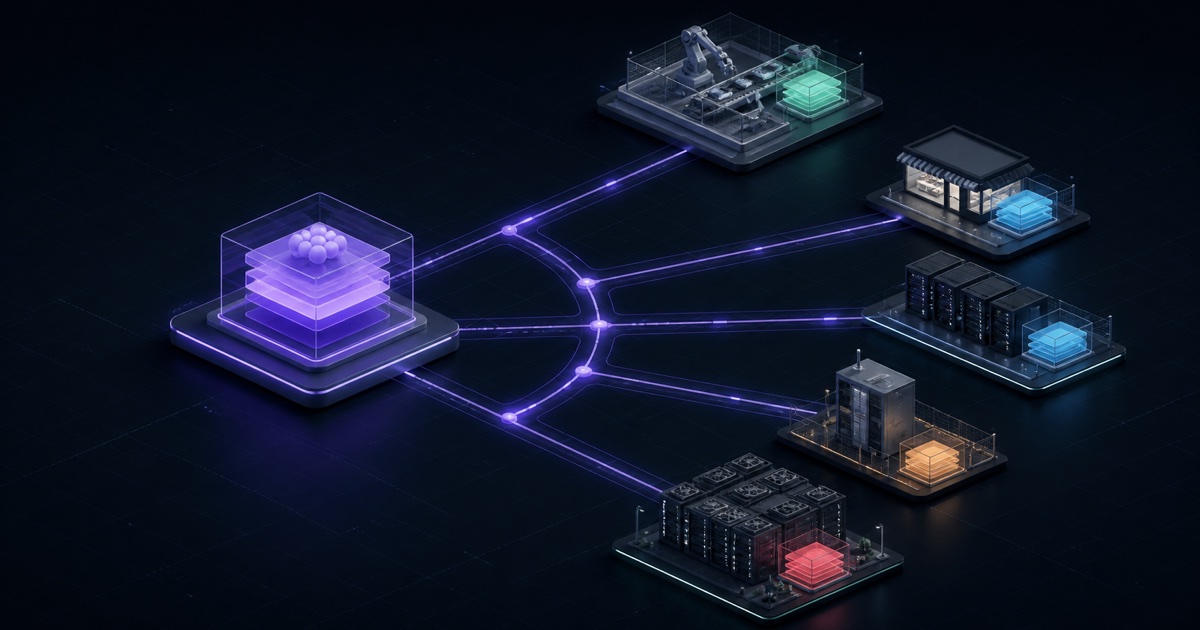 05Deployment guide
A practical framework for taking an AI workload from one successful pilot to a reliable, private, locally tuned rollout across customer sites.
New to local AI?
Field Notes organizes our durable explainers and deployment frameworks into one practical starting point.
Browse field notesBuild closer